5 Gradient Descent and Gradient Boosting
The first part of this chapter shows how to use gradient descent to fit the parameters of prediction functions in the model class \(\Fset\) to the training data \(\Tset\). The second part discusses boosting which moves the prediction function to better fits rather than a parameter vector.
5.1 Gradient descent
5.1.1 The descent step
Write the model class as a family \(f_{\theta}\) indexed by a parameter vector \(\theta\).1For instance, for OLS \(\theta = (\beta_{0},\beta)\). We write \[ \lscr(\theta; x, y) = \lscr(r(y), f_{\theta}(x)) \] for the loss of the parameters \(\theta\) on the single sample \((x,y)\). The training risk \(\hat R_{\Tset}(f_{\theta})\) then becomes a function of \(\theta\) alone, \[ \hat R_{\Tset}(\theta) = \frac{1}{|\Tset|}\sum_{(x,y)\in\Tset}\lscr(\theta; x, y), \] and we look for a \(\theta\) that makes it small. We assume that \(\hat R_{\Tset}\) is differentiable in \(\theta\), so that its gradient \(\nabla\hat R_{\Tset}(\theta)\) exists.
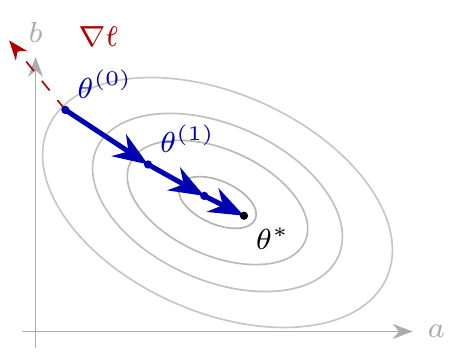
Figure 5.1: Schematic view of gradient descent for a parameter vector \(\theta\). The arrows move opposite to the gradient, crossing level curves toward a minimizer.
The idea is to read the gradient as advice on where to step next, see Fig. 5.1. From Taylor’s formula, for a small step \(\Delta\theta\), \[ \hat R_{\Tset}(\theta + \Delta\theta) \simeq \hat R_{\Tset}(\theta) + \ip{\nabla\hat R_{\Tset}(\theta), \Delta\theta}. \] If \(\nabla\hat R_{\Tset}(\theta) \neq 0\), then \(\theta\) is not a minimizer.2Because \(\hat R_{\Tset}\) is differentiable. The inner product tells us how the risk changes for a small step \(\Delta\theta\). Among all steps of a given length, the one opposite to the gradient makes this inner product as negative as possible,3By the Cauchy-Schwarz inequality. so this is the direction in which the risk drops fastest.4If \(\Delta\theta\) is orthogonal to the gradient, the first-order change in the risk is zero, and then only higher-order terms can change the risk. So take \[ \Delta\theta = -\eta\,\nabla\hat R_{\Tset}(\theta) \] for a learning rate \(\eta>0\) that is small enough to keep Taylor’s approximation valid. Then \[ \hat R_{\Tset}(\theta - \eta\,\nabla\hat R_{\Tset}(\theta)) \simeq \hat R_{\Tset}(\theta) - \eta\norm{\nabla\hat R_{\Tset}(\theta)}^{2} < \hat R_{\Tset}(\theta), \] so the step lowers the risk.
We apply this update rule iteratively, as in Alg. 5.1.1. Writing \(\theta^{(k)}\) for the parameters after \(k\) steps, the iteration reads
\begin{align*} \theta^{(k+1)} - \theta^{(k)} = \Delta \theta^{(k)} = - \eta\,\nabla\hat R_{\Tset}(\theta^{(k)}) \quad \implies \quad \theta^{(k+1)} = \theta^{(k)} - \eta\,\nabla\hat R_{\Tset}(\theta^{(k)}). \tag{5.1.1} \end{align*}The learning rate needs care. If \(\eta\) is very small, it takes many iterations for the algorithm to converge; if \(\eta\) is too large, the steps overshoot and the iterates may diverge.
\begin{algorithm}
\caption{Gradient descent for a parameterized model class.}
\begin{algorithmic}
\State \textbf{Input:} initial parameters $\theta$, learning rate $\eta>0$, tolerance $\epsilon>0$.
\State \textbf{Output:} parameters $\theta$ with a small gradient.
\Procedure{GradientDescent}{$\theta, \eta, \epsilon$}
    \While{$\norm{\nabla\hat R_{\Tset}(\theta)}^{2} > \epsilon$}
        \State $\theta \gets \theta - \eta\, \nabla\hat R_{\Tset}(\theta)$
    \EndWhile
    \Return $\theta$
\EndProcedure
\end{algorithmic}
\end{algorithm}
First, the gradient is an average over the whole training set, which is expensive when \(\Tset\) is large. Second, a zero gradient marks a local minimum only, so where the descent ends can depend on where it starts.
5.1.2 Real-valued labels
Ordinary least squares is the natural first test of the above rule for \(\theta^{(k)}\). Even though we already know how to solve this with linear algebra, running gradient descent on the same problem shows what the iteration computes.
Recall the model class and the objective (3.2.4). A rule in this class predicts \[ \hat y = \beta_{0} + \ip{\beta, x}, \qquad \beta_{0}\in\R, \quad \beta\in\R^{p}, \] so the parameter vector \(\theta = (\beta_{0}, \beta_{1},\ldots,\beta_{p})\) has \(p+1\) components. With squared loss,5The factor \(\tfrac12\) changes no minimizer, so every result of Section 3.2.2 still applies; it only removes a factor \(2\) from the derivatives. the loss on a single sample \((x,y)\) is \[ \lscr(\theta; x, y) = \tfrac12\rb{\beta_{0} + \ip{\beta, x} - y}^{2}, \] and the training risk is the average of these numbers over the training set, \[ \hat R_{\Tset}(\theta) = \frac{1}{2|\Tset|}\sum_{(x,y)\in\Tset}\rb{\beta_{0} + \ip{\beta, x} - y}^{2}. \]
The partial derivatives follow from the chain rule,6\(\partial_{\beta_j} \ip{\beta, x} = x(j)\). applied to one sample at a time:
\begin{align*} \frac{\partial \lscr}{\partial \beta_{0}}(\theta; x,y) &= \beta_{0} + \ip{\beta, x} - y, & \frac{\partial \lscr}{\partial \beta_{j}}(\theta; x,y) &= \rb{\beta_{0} + \ip{\beta, x} - y}\,x(j). \end{align*}The gradient of the training risk is the average of these over \(\Tset\),
\begin{align*} \frac{\partial \hat R_{\Tset}}{\partial \beta_{0}}(\theta) &= \frac{1}{|\Tset|}\sum_{(x,y)\in\Tset}\rb{\beta_{0} + \ip{\beta, x} - y}, \\ \frac{\partial \hat R_{\Tset}}{\partial \beta_{j}}(\theta) &= \frac{1}{|\Tset|}\sum_{(x,y)\in\Tset}\rb{\beta_{0} + \ip{\beta, x} - y}\,x(j), \qquad j = 1,\ldots,p, \end{align*}and these \(p+1\) numbers together form \(\nabla\hat R_{\Tset}(\theta)\).
The update rule is what we get by inserting these derivatives into (5.1.1). Write \(\theta^{(k)} = (\beta_{0}^{(k)}, \beta_{1}^{(k)}, \ldots, \beta_{p}^{(k)})\) for the parameters after \(k\) steps, and \(\hat y^{(k)}(x) = \beta_{0}^{(k)} + \ip{\beta^{(k)}, x}\) for the prediction these parameters make for a feature vector \(x\). Then the step from \(\theta^{(k)}\) to \(\theta^{(k+1)}\) reads
\begin{align*} \beta_{0}^{(k+1)} &= \beta_{0}^{(k)} - \frac{\eta}{|\Tset|} \sum_{(x,y)\in\Tset}\rb{\hat y^{(k)}(x) - y}, \\ \beta_{j}^{(k+1)} &= \beta_{j}^{(k)} - \frac{\eta}{|\Tset|} \sum_{(x,y)\in\Tset}\rb{\hat y^{(k)}(x) - y}\,x(j), \qquad j = 1,\ldots,p. \tag{5.1.2} \end{align*}For the intercept, if the current rule predicts too high on average, the sum is positive and \(\beta_{0}\) comes down. For a weight, each sample contributes its prediction error multiplied by its own \(x(j)\), so samples with a large \(j\)th coordinate have more say in \(\beta_{j}\) than samples with a small one, and samples with \(x(j) = 0\) have none at all.
The learning rate can be discussed concretely here, because the training risk is quadratic in \(\theta\), so its matrix of second derivatives, the Hessian, does not depend on \(\theta\): it is fixed once and for all by the feature values in \(\Tset\). Differentiating the gradient once more with respect to \(\beta_{j}\) gives the average of \(x(j)^{2}\) over the training set, and this is the curvature that the step in the direction of \(\beta_{j}\) has to respect. A single \(\eta\) must serve all \(p+1\) directions at once, and it is the largest curvature that limits how large \(\eta\) may be before the steps overshoot. Suppose now that one feature coordinate is measured in meters and another in kilometers. Their averages of \(x(j)^{2}\) differ by a factor of a million, hence so do the eigenvalues of the Hessian: the rate that keeps the steep direction stable moves the flat one by almost nothing, and progress in that direction takes a million times as many iterations.7The ratio of the largest to the smallest eigenvalue of the Hessian is called the condition number of the problem; the number of iterations needed grows with it. Standardizing the feature coordinates before fitting brings the eigenvalues together, so fewer iterations are needed.
5.1.3 Probability labels
Probabilities as labels occur whenever the observed value is itself a proportion or a probability, for instance, the fraction of trail that is unpaved. The label space is now \(\Yset=[0,1]\), and the affine rule of the previous section will not do, because \(\beta_{0} + \ip{\beta, x}\) ranges over all of \(\R\) and returns values outside \([0,1]\) for \(|x|\) large.
The repair is to squash the affine score into the unit interval with the sigmoid. We first take a single feature, so that the model has two parameters, and
\begin{align*} \hat y = \sigma(z), \qquad z = a x + b, \qquad \sigma(z) = \rb{1+e^{-z}}^{-1}, \tag{5.1.3} \end{align*}with \(\theta = (a,b)\), the weight \(a\) and the bias \(b\). The affine score \(z\) is called the linear predictor or, in the language of neural networks, the logit.
Keeping the squared loss of the previous section, the loss on one sample is \[ \lscr(\theta; x,y) = \tfrac12\rb{\hat y - y}^{2}, \qquad \hat y = \sigma(ax+b). \]
The partial derivatives now need the chain rule twice, since the parameters reach the loss through \(z\) and then through \(\sigma\). The sigmoid has the convenient derivative \[ \sigma'(z) = \sigma(z)\rb{1-\sigma(z)} = \hat y (1-\hat y), \] and \(z=ax+b\) contributes \(\partial z/\partial a = x\) and \(\partial z/\partial b = 1\). Multiplying the three factors,
\begin{align*} \frac{\partial \lscr}{\partial a}(\theta;x,y) &= \rb{\hat y - y}\, \hat y(1-\hat y)\, x, & \frac{\partial \lscr}{\partial b}(\theta;x,y) &= \rb{\hat y - y}\,\hat y(1-\hat y). \end{align*}Writing \(\hat y^{(k)}(x) = \sigma(a^{(k)}x + b^{(k)})\) for the prediction of the current parameters, the update (5.1.1) becomes
\begin{align*} a^{(k+1)} &= a^{(k)} - \frac{\eta}{|\Tset|}\sum_{(x,y)\in\Tset} \rb{\hat y^{(k)}(x) - y}\,\hat y^{(k)}(x)\rb{1-\hat y^{(k)}(x)}\,x, \\ b^{(k+1)} &= b^{(k)} - \frac{\eta}{|\Tset|}\sum_{(x,y)\in\Tset} \rb{\hat y^{(k)}(x) - y}\,\hat y^{(k)}(x)\rb{1-\hat y^{(k)}(x)}. \tag{5.1.4} \end{align*}Three things changed with respect to the previous section, and all three come from the sigmoid. First, there is no closed form to fall back on: setting the derivatives to zero gives equations in which \(a\) and \(b\) sit inside \(\sigma\), so they cannot be separated into a linear system. Second, the training risk need no longer be convex in \(\theta\), so the caveat of the introduction becomes relevant: different starting points may end at different fitted parameters.
Third, and most important for what follows, the factor \(\hat y(1-\hat y)\) is at most \(1/4\), and it is near zero exactly when \(\hat y\) is near \(0\) or \(1\). To see the size of this effect, take \(y=0\) and compare two predictions. A hesitant \(\hat y = 0.5\) contributes \(\rb{\hat y - y}\hat y(1-\hat y) = 0.5\cdot 0.25 = 0.125\) per unit of \(x\) to the sum, while a confidently wrong \(\hat y = 0.999\) contributes \(0.999\cdot 0.000999 \approx 0.001\). The sample that is almost maximally wrong therefore moves the parameters more than a hundred times less than the one that is hesitant. The reason is geometric: \(\hat y\) near \(1\) means \(z = ax+b\) lies far from \(0\), where the sigmoid is flat, so changing \(a\) or \(b\) hardly changes \(\hat y\) and hardly changes the loss. This effect is called saturation.
5.1.4 Binary labels
Binary labels are such that \(y\in\set{0,1}\): the trail edge is bad or it is not, the email is spam or it is not. Since \(\set{0,1}\subset[0,1]\), this is not a new label space at all, and the model (5.1.3) can stay exactly as it is. What changes is what we may say about the label. A fraction is a number we simply observe, and the loss that compares it with a prediction is ours to choose. A binary label is the outcome of a draw, and if we are willing to model that draw, then the loss follows from the model instead of being chosen by hand.
So assume that, given the features, the labels are independent, and that the model returns the probability of the outcome \(y=1\), \[ \P{Y = 1 \mid x} = \hat y = \sigma(ax+b). \] Then a sample with \(y=1\) has probability \(\hat y\) and one with \(y=0\) has probability \(1-\hat y\), which the single expression \(\hat y^{y}(1-\hat y)^{1-y}\) covers, so the likelihood of the observed labels is \[ L(a,b) = \prod_{(x,y)\in\Tset} \hat y(x)^{\,y}\rb{1-\hat y(x)}^{1-y}. \] The parameters that make the observed labels most probable are those that maximize \(L\), and because the logarithm is increasing, they are also the ones that minimize \(-\log L\), and hence \(-\log L/|\Tset|\). This average is the training risk \(\hat R_{\Tset}(a,b)\) when the loss on a single sample is the binary cross-entropy loss,
\begin{align*} \lscr(\theta; x,y) = -y\log \hat y - (1-y)\log(1-\hat y). \tag{5.1.5} \end{align*}The partial derivatives are again a chain rule. Using \(\sigma'(z) = \hat y(1-\hat y)\) once more,
\begin{align*} \frac{\partial}{\partial a}\log \hat y &= \frac{\hat y (1-\hat y)}{\hat y}\frac{\partial z}{\partial a} = (1-\hat y)x, & \frac{\partial}{\partial b}\log \hat y &= 1-\hat y, \end{align*}and the same calculation for \(\log(1-\hat y)\) gives
\begin{align*} \frac{\partial}{\partial a}\log(1-\hat y) &= -\hat y x, & \frac{\partial}{\partial b}\log(1-\hat y) &= -\hat y. \end{align*}Hence,
\begin{align*} \frac{\partial \lscr}{\partial a}(\theta;x,y) &= -\rb{y(1-\hat y)x - (1-y)\hat y x} = \rb{\hat y - y}x, & \frac{\partial \lscr}{\partial b}(\theta;x,y) &= \hat y - y. \end{align*}The update rule becomes
\begin{align*} a^{(k+1)} &= a^{(k)} - \frac{\eta}{|\Tset|}\sum_{(x,y)\in\Tset} \rb{\hat y^{(k)}(x) - y}\,x, & b^{(k+1)} &= b^{(k)} - \frac{\eta}{|\Tset|}\sum_{(x,y)\in\Tset} \rb{\hat y^{(k)}(x) - y}. \end{align*}Compare this with (5.1.4): the model is the same, the data are the same, and the factor \(\hat y(1-\hat y)\) has disappeared. The gradient that remains is the prediction error itself, exactly as it was for OLS. So a confidently wrong prediction, which the squared loss almost ignores, produces the largest correction the cross-entropy can give, and saturation is gone.
The training risk under the cross-entropy loss is moreover convex in \(\theta\), so every point with zero gradient is a global minimizer, and the second limitation of the descent step does not apply. With more features this model is two-class logistic regression.
For neural networks the training risk is not convex, and different starting points can end at different fitted parameters.
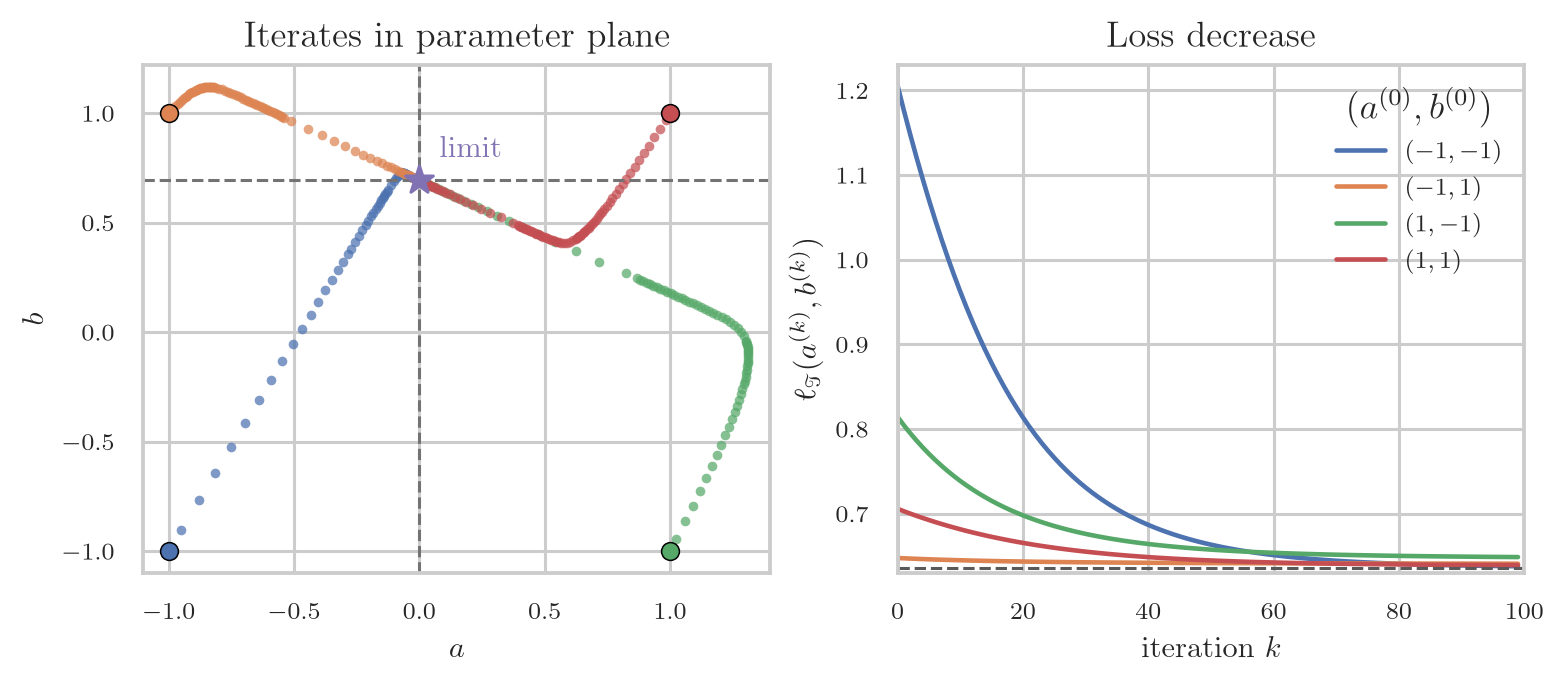
Alg. 5.1.2 collects the steps, and Fig. 5.2 shows them running from four starting points. All four converge to the same limit, and the training risk falls quickly at first while the parameters themselves are still moving slowly.
\begin{algorithm}
\caption{Gradient descent for a sigmoid with binary labels.}
\begin{algorithmic}
\State \textbf{Input:} training set $\Tset$, learning rate $\eta>0$, tolerance $\epsilon>0$.
\State \textbf{Output:} parameters $a, b$.
\State Choose initial values $a,b$.
\While{$\norm{\nabla\hat R_{\Tset}(a,b)}^{2} > \epsilon$}
  \State Compute $\hat y \gets\sigma(ax+b)$ for every $(x,y) \in \Tset$.
  \State $\nabla_a \gets \frac{1}{|\Tset|}\sum_{(x,y)\in\Tset}(\hat y-y)x$, $\nabla_b \gets \frac{1}{|\Tset|}\sum_{(x,y)\in\Tset}(\hat y-y)$.
  \State $a \gets a - \eta\, \nabla_a$, $b \gets b - \eta\, \nabla_b$.
\EndWhile
\Return $a,b$
\end{algorithmic}
\end{algorithm}
5.1.5 Stochastic and mini-batch gradient descent
The cost per step of (5.1.2) is one pass over the entire training set. When the training set is large, this is the dominant cost of fitting, and it has to be paid again at every iteration.
Stochastic gradient descent8Wikipedia: Stochastic approximation. replaces the gradient over the entire set \(\Tset\) in (5.1.1) by the gradient of a single sample \((X,Y)\) drawn uniformly from \(\Tset\). This replacement is unbiased,
\begin{align*} \E{\nabla\lscr(\theta; X, Y)} = \frac{1}{|\Tset|}\sum_{(x,y)\in\Tset}\nabla\lscr(\theta; x,y) = \nabla\hat R_{\Tset}(\theta), \end{align*}because a uniform draw gives each of the \(|\Tset|\) samples probability \(1/|\Tset|\), so that the expectation is precisely the average that defines the full gradient. Thus the update \( \theta^{(k+1)} = \theta^{(k)} - \eta\,\nabla\lscr(\theta^{(k)}; X, Y) \) moves, on expectation, in the same direction as the full gradient descent of (5.1.1). The advantage is that each step is cheap as it uses the gradient of just one sample. The disadvantage is that the sequence of updates is noisy, as each step depends only on the sample that happens to be drawn.
Mini-batching is a compromise often used in practice. Instead of one sample, choose a batch \(\Bset\), a set of samples drawn at random from \(\Tset\) without replacement,9The batch size controls the tradeoff between cost and noise. There is no universally best size for \(\Bset\). Small \(\Bset\) is cheap but noisy. Large \(\Bset\) is stable, but uses more memory and computation. Sizes are usually powers of two between \(32\) and \(256\). and use the gradient of the empirical risk on that batch,
\begin{align*} \nabla\hat R_{\Bset}(\theta) = \frac{1}{|\Bset|}\sum_{(x,y)\in\Bset}\nabla\lscr(\theta;x,y), \tag{5.1.6} \end{align*}as an approximation of the full gradient. By the same argument as for stochastic gradient descent, \(\E{\nabla\hat R_{\Bset}(\theta)}=\nabla\hat R_{\Tset}(\theta)\). Thus mini-batch gradient descent still moves in the correct direction on average, but it is less noisy than pure stochastic gradient descent.
We still want every training sample in \(\Tset\) to contribute to the parameter updates. We do this by splitting the training set \(\Tset\) at random into disjoint batches and using each batch, in turn, to compute the mini-batch gradient in (5.1.6). One training epoch consists of one round in which all batches have been used once. One epoch contains \(\lceil |\Tset|/|\Bset|\rceil\) parameter updates.10When \(|\Bset|\) does not divide \(|\Tset|\), the last batch has fewer than \(|\Bset|\) samples.
Reshuffling the samples into new batches at the start of each epoch is important: it prevents the same samples from always appearing together.
5.2 Gradient Boosting
Boosting11Wikipedia: Gradient boosting. is an algorithm that builds one prediction function by adding simple functions such as shallow trees one at a time. These simple functions are such that they are corrections on the samples where the prediction function performs badly. Where gradient descent lowers the training risk by moving a parameter vector against the gradient, boosting lowers the training risk by moving the prediction function against the gradient.
The labels are numbers in all cases we consider below, so \(r(y) = y\), and we write \(\lscr(y, a)\) for the loss of the prediction \(a\) on a sample with label \(y\).
We discuss the main ideas of gradient boosting first, then we apply it to regression and classification.
5.2.1 The general idea
Fix a base class \(\Hset\) of prediction functions. Its members are called base learners or weak learners: each is a simple rule that, on its own, predicts only slightly better than guessing. A decision stump, a tree of depth one, is the simplest example.
Boosting is an ensemble method, like bagging, but the ensemble is a sum rather than an average. After \(B\) rounds the prediction function is the additive model
\begin{align*} f_B(x) = f_0(x) + \eta\sum_{b=1}^{B} \rho_b\, h_b(x), \end{align*}with base learners \(h_b \in \Hset\), coefficients \(\rho_b \in \R\), a learning rate \(\eta > 0\), and a starting function \(f_0\). Each \(h_b\) is simple, but the sum \(f_B\) need not be: with stumps as base learners and a single feature, \(f_B\) is a step function with up to \(B\) jumps. The model class \(\Fset\) of Chapter 3 is here the set of all such sums. It grows with \(B\), since every extra round adds one more function to the sum, so a larger \(B\) permits a closer fit of the training set.
The terms are not chosen jointly. Boosting happens forward stagewise: at round \(b\) it holds \(f_{b-1}\) fixed and then asks for the pair \((h_b, \rho_b)\) that lowers the training risk \(\hat R_\Tset\) most:
\begin{align*} (h_b, \rho_b) &\in \argmin_{h \in \Hset,\, \rho \in \R} \frac{1}{n}\sum_{(x,y) \in \Tset} \lscr\rb{y, f_{b-1}(x) + \rho\, h(x)}, & n &= |\Tset|. \tag{5.2.1} \end{align*}Then it uses this pair to update
\begin{align*} f_b(x) = f_{b-1}(x) + \eta\, \rho_b\, h_b(x). \tag{5.2.2} \end{align*}Once a term has been added it is never revisited. Each round is therefore one small fitting problem instead of a joint search over \(B\) base learners at once. It also makes boosting greedy: nothing guarantees that \(f_B\) is the best sum of \(B\) members of \(\Hset\).
The learning rate \(\eta\) scales every correction; with smaller \(\eta\) more rounds are needed to reach the same fit.
Any class \(\Hset\) can be used in principle, but shallow regression trees are the usual choice. A tree splits on the features themselves and can capture non-linear behavior. Second, fitting a tree of small depth is fast, which matters when the fit is repeated \(B\) times. Third, shallow trees have low variance. The problem that a single weak learner is highly biased is mitigated by forming an ensemble.
Gradient boosting is a three step approach to approximate (5.2.1). The problem is that the training risk depends on \(f\) only through the \(n\) numbers \(f(x_1), \ldots, f(x_n)\), so we need to find a way to use these numbers to improve \(f\).
Write \(a = (a_1, \ldots, a_n)\) with \(a_i = f(x_i)\), and \(a^{(b-1)} = (f_{b-1}(x_1), \ldots, f_{b-1}(x_n))\) for the predictions of the current \(f_{b-1}\). Then the gradient \( \left.\nabla_a \hat R_{\Tset}(a) \right|_{a = a^{(b-1)}} \) has as \(i\)th component
\begin{align*} \left.\frac{\partial}{\partial a_i} \frac1n \sum_{j=1}^{n} \lscr(y_j, a_j) \right|_{a = a^{(b-1)}} = \left. \frac1n \frac{\partial \lscr(y_i, a)}{\partial a} \right|_{a = f_{b-1}(x_i)}. \end{align*}By dropping the factor12This only rescales the step. \(1/n\) we obtain the pseudo-residual
\begin{align*} \rscr_i^{(b)} = -\left.\frac{\partial \lscr(y_i, a)}{\partial a}\right|_{a = f_{b-1}(x_i)}, \qquad i = 1, \ldots, n. \tag{5.2.3} \end{align*}This residual says whether the prediction at \(x_i\) should go up or down to lower the loss of sample \(i\). Together, \[ (\rscr_1^{(b)}, \ldots, \rscr_n^{(b)}) = - n \left.\nabla_a \hat R_{\Tset}(a) \right|_{a = a^{(b-1)}} \] is the direction of steepest decrease of the training risk at the training points.
The next step in gradient boosting is to fit a base learner to the pseudo-residuals by treating the pairs \((x_i, \rscr_i^{(b)})\) as a regression problem with squared loss:
\begin{align*} h_b \in \argmin_{h \in \Hset} \sum_{i=1}^{n} \rb{\rscr_i^{(b)} - h(x_i)}^{2}. \tag{5.2.4} \end{align*}The result is a function that is a member of \(\Hset\) closest to the negative gradient in the squared sense.13Of course, it is not the negative gradient itself. Observe that the squared loss in (5.2.4) is a fitting device; it is unrelated to the loss \(\lscr\) of the prediction problem itself. Square loss is used because a regression tree of Chapter 4 fitted with this loss stores the mean of the fitted values in each leaf, so its leaf values follow in closed form.
Each weak learner14In practice often a shallow tree is fitted to \(\rscr_i^{(b)}\), not to \(y_i\). A sample with a large \(|\rscr_i^{(b)}|\) is one the current ensemble predicts badly, and it calls for a large correction; a sample with \(\rscr_i^{(b)} \approx 0\) is already predicted well and calls for none. Since a sample contributes the square of its residual to the objective in (5.2.4), a split that reduces a large residual lowers that objective more than one that improves an already small residual, so samples with large remaining errors have more influence on the splits of the next tree. No sample weights are assigned here; the emphasis comes from the residuals themselves.
The third and last step in computing (5.2.2) is to find a good scale factor \(\rho_b\).15The fitted \(h_b\) only approximates the direction, and the scale need not be right. For this, we can use a line search:
\begin{align*} \rho_b \in \argmin_{\rho \in \R} \sum_{i=1}^{n} \lscr\rb{y_i, f_{b-1}(x_i) + \rho\, h_b(x_i)}. \tag{5.2.5} \end{align*}We can now update (5.2.2) to get \(f_b\).
The iteration has to start somewhere. The natural start is the best constant rule of Chapter 3:
\begin{align*} f_0(x) = c^{*} \in \argmin_{c \in \R} \sum_{i=1}^{n} \lscr(y_i, c). \tag{5.2.6} \end{align*}Alg. 5.2.1 collects the steps.
\begin{algorithm}
\caption{Gradient boosting for a differentiable loss \(\lscr\).}
\begin{algorithmic}
\State \textbf{Input:} a training set $\Tset$, a base class $\Hset$, the number $B$ of rounds, a learning rate $\eta > 0$.
\State \textbf{Output:} a prediction function $f_B$.
\Procedure{GradientBoost}{$\Tset, \Hset, B, \eta$}
    \State $f_{0} \gets \argmin_{c \in \R} \sum_{(x,y) \in \Tset} \lscr(y, c)$.
    \For{$b = 1, \ldots, B$}
        \State $\rscr_i^{(b)} \gets -\left.\dfrac{\partial \lscr(y_i, a)}{\partial a}\right|_{a = f_{b-1}(x_i)}$ for all $i$ \Comment{Negative gradient.}
        \State $h_b \gets \argmin_{h \in \Hset} \sum_{i} \rb{\rscr_i^{(b)} - h(x_i)}^{2}$ \Comment{Fit a base learner.}
        \State $\rho_b \gets \argmin_{\rho \in \R} \sum_{i} \lscr\rb{y_i, f_{b-1}(x_i) + \rho h_b(x_i)}$ \Comment{Line search.}
        \State $f_b \gets f_{b-1} + \eta\, \rho_b\, h_b$
    \EndFor
    \Return $f_B$
\EndProcedure
\end{algorithmic}
\end{algorithm}
We next apply gradient boosting to a regression and a classification problem.
5.2.2 Regression boosting
Take the regression setting of Section 3.2.2, \(\Yset = \Aset = \R\), with the loss
\begin{align*} \lscr(y, a) = \tfrac12 (y-a)^{2}. \end{align*}The initialization (5.2.6) is the constant that minimizes \(\sum_i (y_i-c)^{2}\), which is the sample mean \(\bar y\), as derived in Section 3.2.2. Then \(-\partial \lscr(y,a)/\partial a = y - a\), so (5.2.3) gives
\begin{align*} \rscr_i^{(b)} = y_i - f_{b-1}(x_i). \end{align*}The first residuals \(\rscr_i^{(1)} = y_i - \bar y\) are the part of each label that a single constant cannot explain. Fit a shallow regression tree \(h_1\) to the pairs \((x_i, \rscr_i^{(1)})\); by (5.2.4) this is an ordinary least-squares tree fit with the residuals as labels. Below we show that the line search gives \(\rho_b=1\). Thus, it suffices to add a fraction \(\eta\) of this tree to the constant, recompute the residuals \(\rscr_i^{(2)} = y_i - f_1(x_i)\), fit the next tree to those, and so on; we have all ingredients to operate Alg. 5.2.1.
To see that the line search gives \(\rho_b =1\), use \(\rscr_i^{(b)} = y_i - f_{b-1}(x_i)\) to write the objective of (5.2.5) as \(\tfrac12\sum_i (\rscr_i^{(b)} - \rho h_b(x_i))^{2}\), set its derivative with respect to \(\rho\) to zero, and simplify:16Provided \(\sum_i h_b(x_i)^{2} > 0\); a tree with all leaf values zero adds nothing.
\begin{align*} \rho_b = \frac{\sum_i \rscr_i^{(b)} h_b(x_i)}{\sum_i h_b(x_i)^{2}}. \end{align*}Write \(\set{\Tset_1, \ldots, \Tset_m}\) for the partition of the training samples formed by the leaves of \(h_b\), as in (4.1.1), and \(c_t\) for the value stored in leaf \(t\). A least-squares regression tree stores in each leaf the mean of the values it was fitted on, so \(c_t=|\Tset_t|^{-1}\sum_{i \in \Tset_t} \rscr_i^{(b)}\), hence \(\sum_{i\in\Tset_t} \rscr_i^{(b)}=|\Tset_t| c_t\). Summing over the leaves,
\begin{align*} \sum_i \rscr_i^{(b)} h_b(x_i) = \sum_{t=1}^{m} c_t \sum_{i \in \Tset_t} \rscr_i^{(b)} = \sum_{t=1}^{m} |\Tset_t| c_t^{2} = \sum_i h_b(x_i)^{2}. \end{align*}The sum of squared residuals decreases at every step. Let \(\Tset_t\) be the samples in a leaf, as in (4.1.1), and write \(c_t\) for the mean residual on that leaf. Since \(\rho_b = 1\), the update (5.2.2) replaces each \(\rscr_{i}^{(b)}\) by \(\rscr_{i}^{(b)} - \eta c_t\), which turns the sum of squares on that leaf into
\begin{align*} \sum_{i\in \Tset_t} (\rscr_{i}^{(b)} - \eta c_t)^{2} = \sum_{i\in \Tset_t} (\rscr_{i}^{(b)})^{2} - 2\eta c_t \sum_{i\in \Tset_t}\rscr_{i}^{(b)} + |\Tset_t|\,\eta^{2}c_t^{2} = \sum_{i\in \Tset_t} (\rscr_{i}^{(b)})^{2} - \eta(2-\eta)\,|\Tset_t|\,c_t^{2}, \end{align*}using \(\sum_{i\in\Tset_t}\rscr_{i}^{(b)} = |\Tset_t|\,c_t\). Since \(\eta(2-\eta) > 0\) for every \(\eta\in(0,2)\), which covers the small \(\eta\) used in practice, the decrease is strict on a leaf whose mean residual is nonzero. Summing over leaves gives the claim for the whole training set.
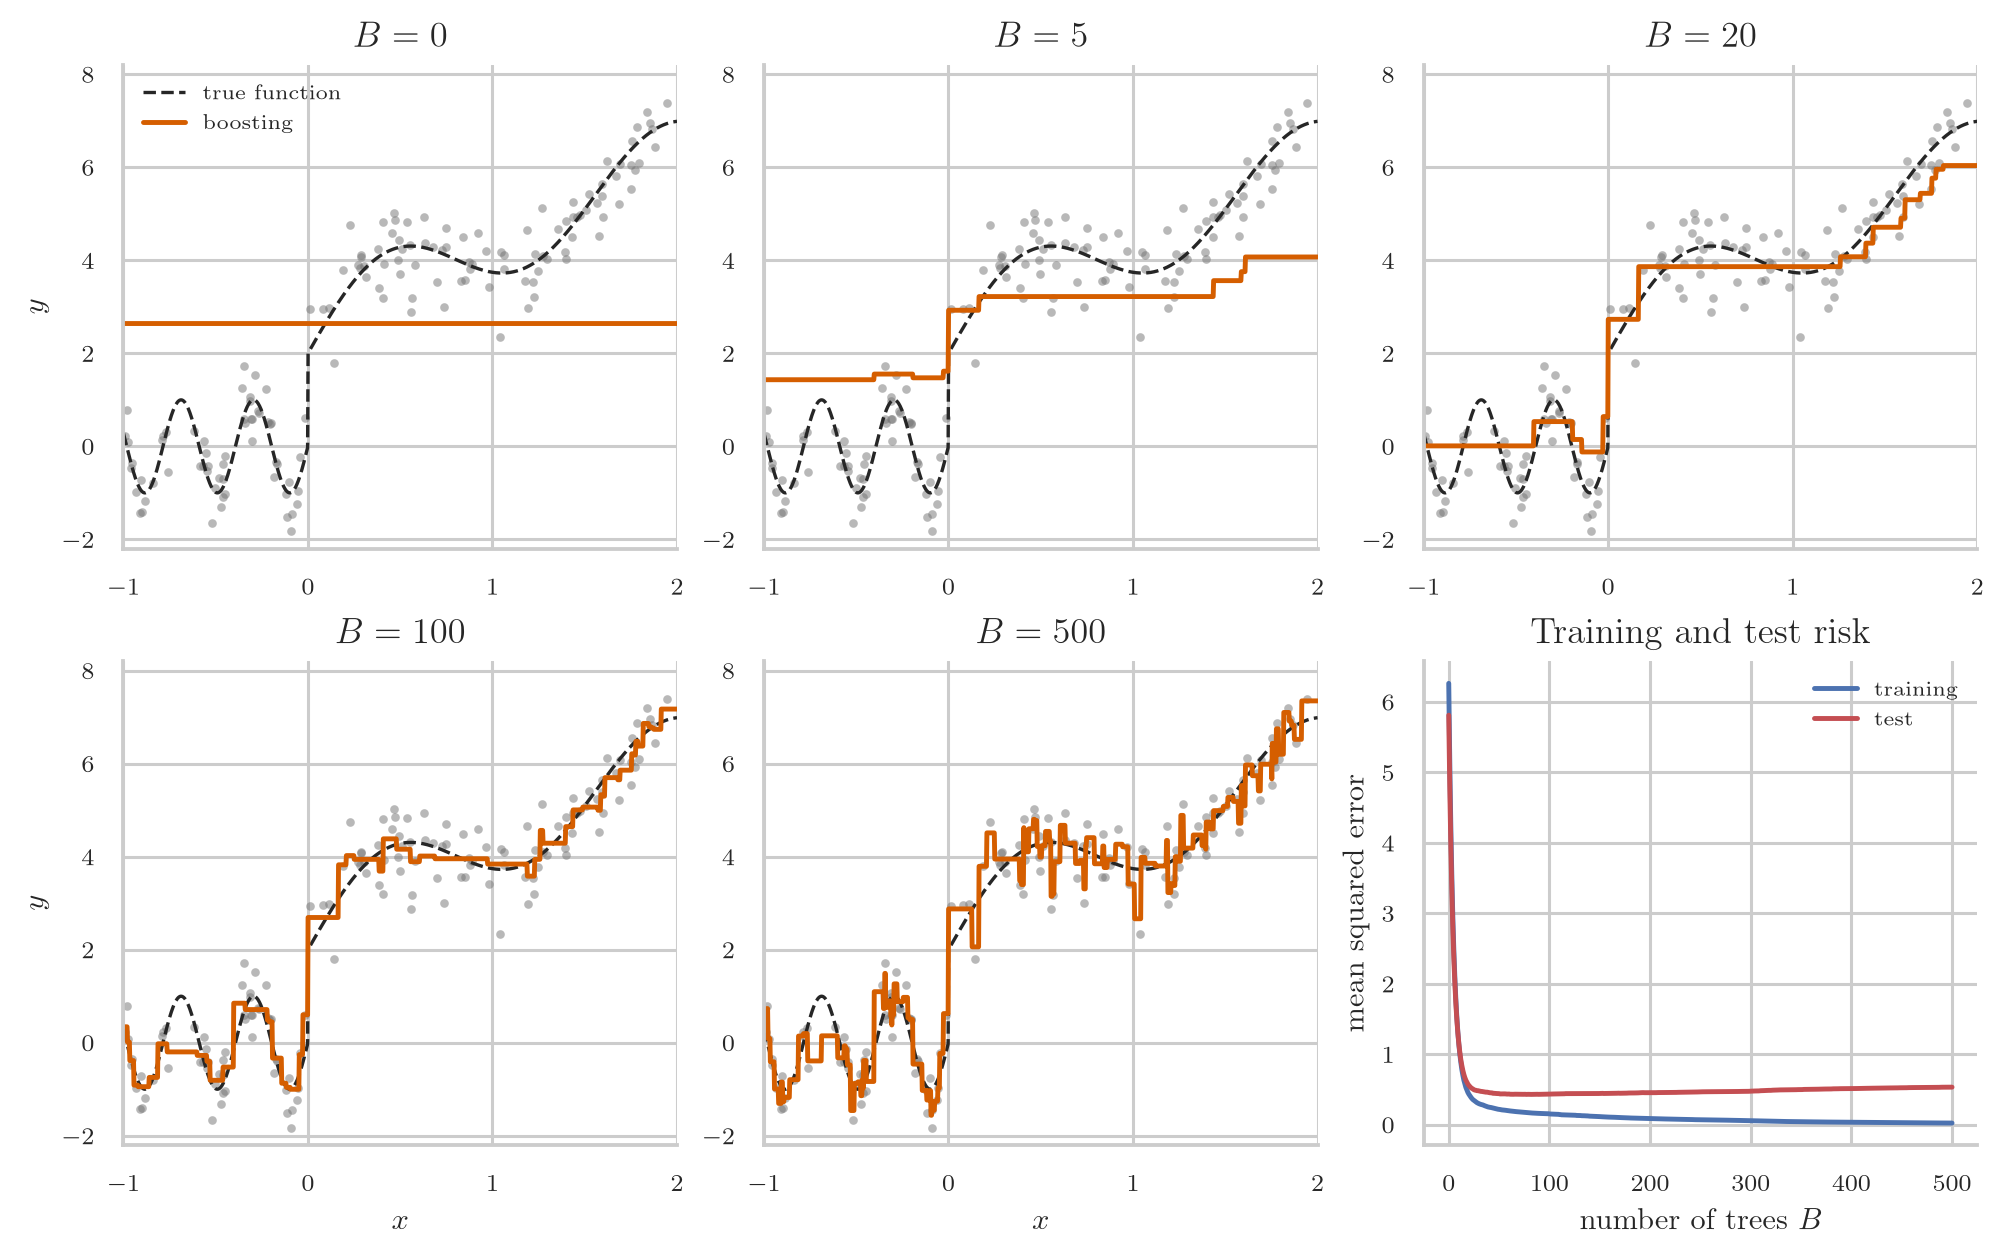
The training risk therefore keeps falling as trees are added. However, the risk on new samples does not: at first the added trees pick up structure that the earlier ones missed and the validation risk falls with the training risk, but after enough rounds the added trees fit the training samples only, and the validation risk rises again. Fig. 5.3 provides an example.
5.2.3 Classification boosting
We will show how the steps of gradient boosting can be applied to classification. This is known as AdaBoost.17Wikipedia: AdaBoost. Wikipedia: XGBoost is an implementation of gradient tree boosting.
Take binary classification with18The two labels are a relabeling of the \(\set{0,1}\) convention used elsewhere in the book. The point of the relabeling is that below the sign of \(y f(x)\) tells whether a prediction is correct, and \(y h(x) \in \set{-1, 1}\) for a base learner \(h\).
\begin{align*} \Yset = \set{-1, +1}, \qquad \Aset = \R. \end{align*}The prediction \(f(x)\in\R\) is a score, and the decision map of (3.1.1) is
\begin{align*} \hat y = d(f(x)) = \sign(f(x)). \end{align*}The quantity
\begin{align*} y f(x) \end{align*}is the margin of the sample \((x,y)\). It is positive when the sign of the score matches the label, so the classification is correct, and negative when it does not.
The base class is a set of stumps that map to \(\set{-1, 1}\),
\begin{align*} \Hset \subset \set{h : \Xset \to \set{-1, +1}}. \end{align*}To compute the pseudo residuals, the derivative of the loss should be meaningful. Zero-one loss is \(\1{y \neq \sign(f(x))} = \1{y f(x) < 0}\). As this is a step function of the margin, it has derivative zero wherever it is differentiable, so this is useless as a loss function. AdaBoost replaces this loss by the exponential loss
\begin{align*} \lscr(y, a) = e^{-y a}, \tag{5.2.7} \end{align*}which is differentiable, decreasing in the margin, and satisfies \(\1{ya<0} \le e^{-ya}\) for all \(ya\). So the training risk under exponential loss is an upper bound for the training risk under zero-one loss, and pushing the first down pushes the second down with it.
Differentiating (5.2.7) gives \(\partial \lscr(y,a)/\partial a = -y e^{-ya}\), so (5.2.3) reads
\begin{align*} \rscr_i^{(b)} = y_i \tilde w_i^{(b)}, \qquad \tilde w_i^{(b)} := e^{-y_i f_{b-1}(x_i)}. \tag{5.2.8} \end{align*}Thus the pseudo-residual of sample \(i\) factors into a label and a positive number \(\tilde w_i^{(b)}\) that depends only on the margin. A sample with a large positive margin has \(\tilde w_i^{(b)}\) close to \(0\); a misclassified sample has margin below \(0\) and hence \(\tilde w_i^{(b)} > 1\). By normalizing
\begin{align*} w_i^{(b)} = \frac{\tilde w_i^{(b)}}{\sum_{j=1}^{n} \tilde w_j^{(b)}}, \qquad \sum_{i=1}^{n} w_i^{(b)} = 1, \tag{5.2.9} \end{align*}\(w^{(b)}\) becomes a probability vector over the training samples.
This normalization is the softmax function \(\sm\), which maps a vector \(s\) of real numbers to a probability vector by
\begin{align*} \sm_{k}(s) = \frac{e^{s_{k}}}{\sum_{j} e^{s_{j}}}, \tag{5.2.10} \end{align*}so that larger scores receive larger probabilities. Indeed, (5.2.9) is \(w^{(b)} = \sm(s^{(b)})\) with scores \(s_i^{(b)} = -y_i f_{b-1}(x_i)\), the negated margins. Here the index runs over the \(n\) training samples, so the softmax produces a pmf over samples; in classification it runs over the classes instead.
The next step in gradient boosting is the square loss optimization over \(h_b\). Substitute (5.2.8) into the fitting step (5.2.4) and expand the square:
\begin{align*} \sum_{i=1}^{n} \rb{\rscr_i^{(b)} - h(x_i)}^{2} = \sum_{i=1}^{n} \rb{\rscr_i^{(b)}}^{2} - 2\sum_{i=1}^{n} \rscr_i^{(b)} h(x_i) + \sum_{i=1}^{n} h(x_i)^{2}. \end{align*}The first sum does not involve \(h\). The third equals \(n\), because \(h(x_i)^{2}=1\) for every \(h \in \Hset\). Therefore,
\begin{align*} \argmin_{h\in \Hset}\sum_i \rb{\rscr_i^{(b)} - h(x_i)}^{2} = \argmax_{h\in \Hset} \sum_i \tilde w_i^{(b)} y_i h(x_i). \end{align*}Rewriting this sum in terms of the misclassified samples prepares the line search over \(\rho_b\). Since \(y_i\) and \(h(x_i)\) both lie in \(\set{-1,+1}\),
\begin{align*} y_i h(x_i) = 1 - 2\cdot\1{y_i \neq h(x_i)}, \end{align*}so that, dividing by the positive constant \(\sum_j \tilde w_j^{(b)}\),
\begin{align*} \frac{\sum_i \tilde w_i^{(b)} y_i h(x_i)}{\sum_j \tilde w_j^{(b)}} = 1 - 2 \err_{b}(h), \end{align*}where the weighted misclassification error is given by
\begin{align*} \err_b(h) = \sum_{i=1}^{n} w_i^{(b)} \1{y_i \neq h(x_i)}. \tag{5.2.11} \end{align*}With this, the fitting step (5.2.4) becomes
\begin{align*} h_b \in \argmin_{h \in \Hset} \err_b(h). \tag{5.2.12} \end{align*}The line search has a simple solution.
Theorem 5.2.1.
For classification boosting, the optimal scale factor is
\begin{align*} \rho_b &= \frac12 \log\frac{1-\err_b}{\err_b}, & \err_b &= \err_b(h_b). \tag{5.2.13} \end{align*}Proof
For the line search (5.2.5) \[ \argmin_{\rho \in \R} \sum_{i} \lscr\rb{y_i, f_{b-1}(x_i) + \rho h_b(x_i)} \] split the sum by whether \(h_b\) classifies sample \(i\) correctly, using \(y_i h_b(x_i) = \pm 1\):
\begin{align*} \sum_{i=1}^{n} e^{-y_i (f_{b-1}(x_i) + \rho h_b(x_i))} = \sum_{i=1}^{n} \tilde w_i^{(b)} e^{-\rho y_i h_b(x_i)} = e^{-\rho} \sum_{i=1}^{n} \tilde w_i^{(b)} + e^{\rho} \sum_{i=1}^{n} \tilde w_i^{(b)} \1{y_{i} \neq h_{b}(x_{i})}. \end{align*}Dividing by \(\sum_j \tilde w_j^{(b)}\) leaves the minimizer unchanged and replaces \(\tilde w\) by \(w\). With (5.2.11) the two sums become \(1-\err_b\) and \(\err_b\), so we must minimize
\begin{align*} G(\rho) = e^{-\rho}(1-\err_b) + e^{\rho}\err_b. \tag{5.2.14} \end{align*}This is a function of one variable with \(G''(\rho) = e^{-\rho}(1-\err_b) + e^{\rho}\err_b > 0\) whenever \(0 < \err_b < 1\), hence strictly convex, so the stationary point is the minimum. From \(G'(\rho) = -e^{-\rho}(1-\err_b) + e^{\rho}\err_b = 0\) and solving for \(\rho_{b}\) the result follows.
A classifier guesses better than random when \(\err_b < 1/2\), in which case \(\rho_b > 0\); one that guesses, \(\err_b = 1/2\), gets \(\rho_b = 0\) and is not added at all.19When \(\err_{b} > 1/2\), use \(-h_b\) as the improvement. The requirement \(\err_b < 1/2\) is known as the weak-learning condition.
Observe that in the above we used the weights \(w^{(b)}\), which in turn depend on \(f_{b-1}\) through (5.2.9). Once we have the update \(h_b\), we need to update these weights for the next iteration. Using the update (5.2.2),
\begin{align*} \tilde w_i^{(b+1)} = e^{-y_i f_b(x_i)} = e^{-y_i f_{b-1}(x_i)} e^{-\eta \rho_b y_i h_b(x_i)} = \tilde w_i^{(b)} e^{-\eta \rho_b y_i h_b(x_i)}, \end{align*}and after normalizing,
\begin{align*} w_i^{(b+1)} = \frac{w_i^{(b)} e^{-\eta \rho_b y_i h_b(x_i)}} {\sum_{j=1}^{n} w_j^{(b)} e^{-\eta \rho_b y_j h_b(x_j)}}. \tag{5.2.15} \end{align*}Since \(y_i h_b(x_i) = \pm 1\), the numerator multiplies \(w_i^{(b)}\) by \(e^{-\eta\rho_b} < 1\) when sample \(i\) is classified correctly and by \(e^{\eta\rho_b} > 1\) when it is not. Samples that the new classifier gets wrong gain weight, and by (5.2.12) the next classifier is chosen to do better on exactly those samples.
For the initialization (5.2.6), let \(n_+\) and \(n_-\) count the samples with \(y_i = +1\) and \(y_i = -1\). Then \(\sum_i e^{-y_i c} = n_+ e^{-c} + n_- e^{c}\), and setting its derivative to zero gives \(f_0(x) = \frac12 \log(n_+/n_-)\). AdaBoost as usually stated takes \(f_0 = 0\) instead, which by (5.2.9) starts the weights uniform at \(w_i^{(1)} = 1/n\), and takes \(\eta=1\), so that each classifier enters with its full coefficient \(\rho_b\).
Fig. 5.4 shows an example of AdaBoost.
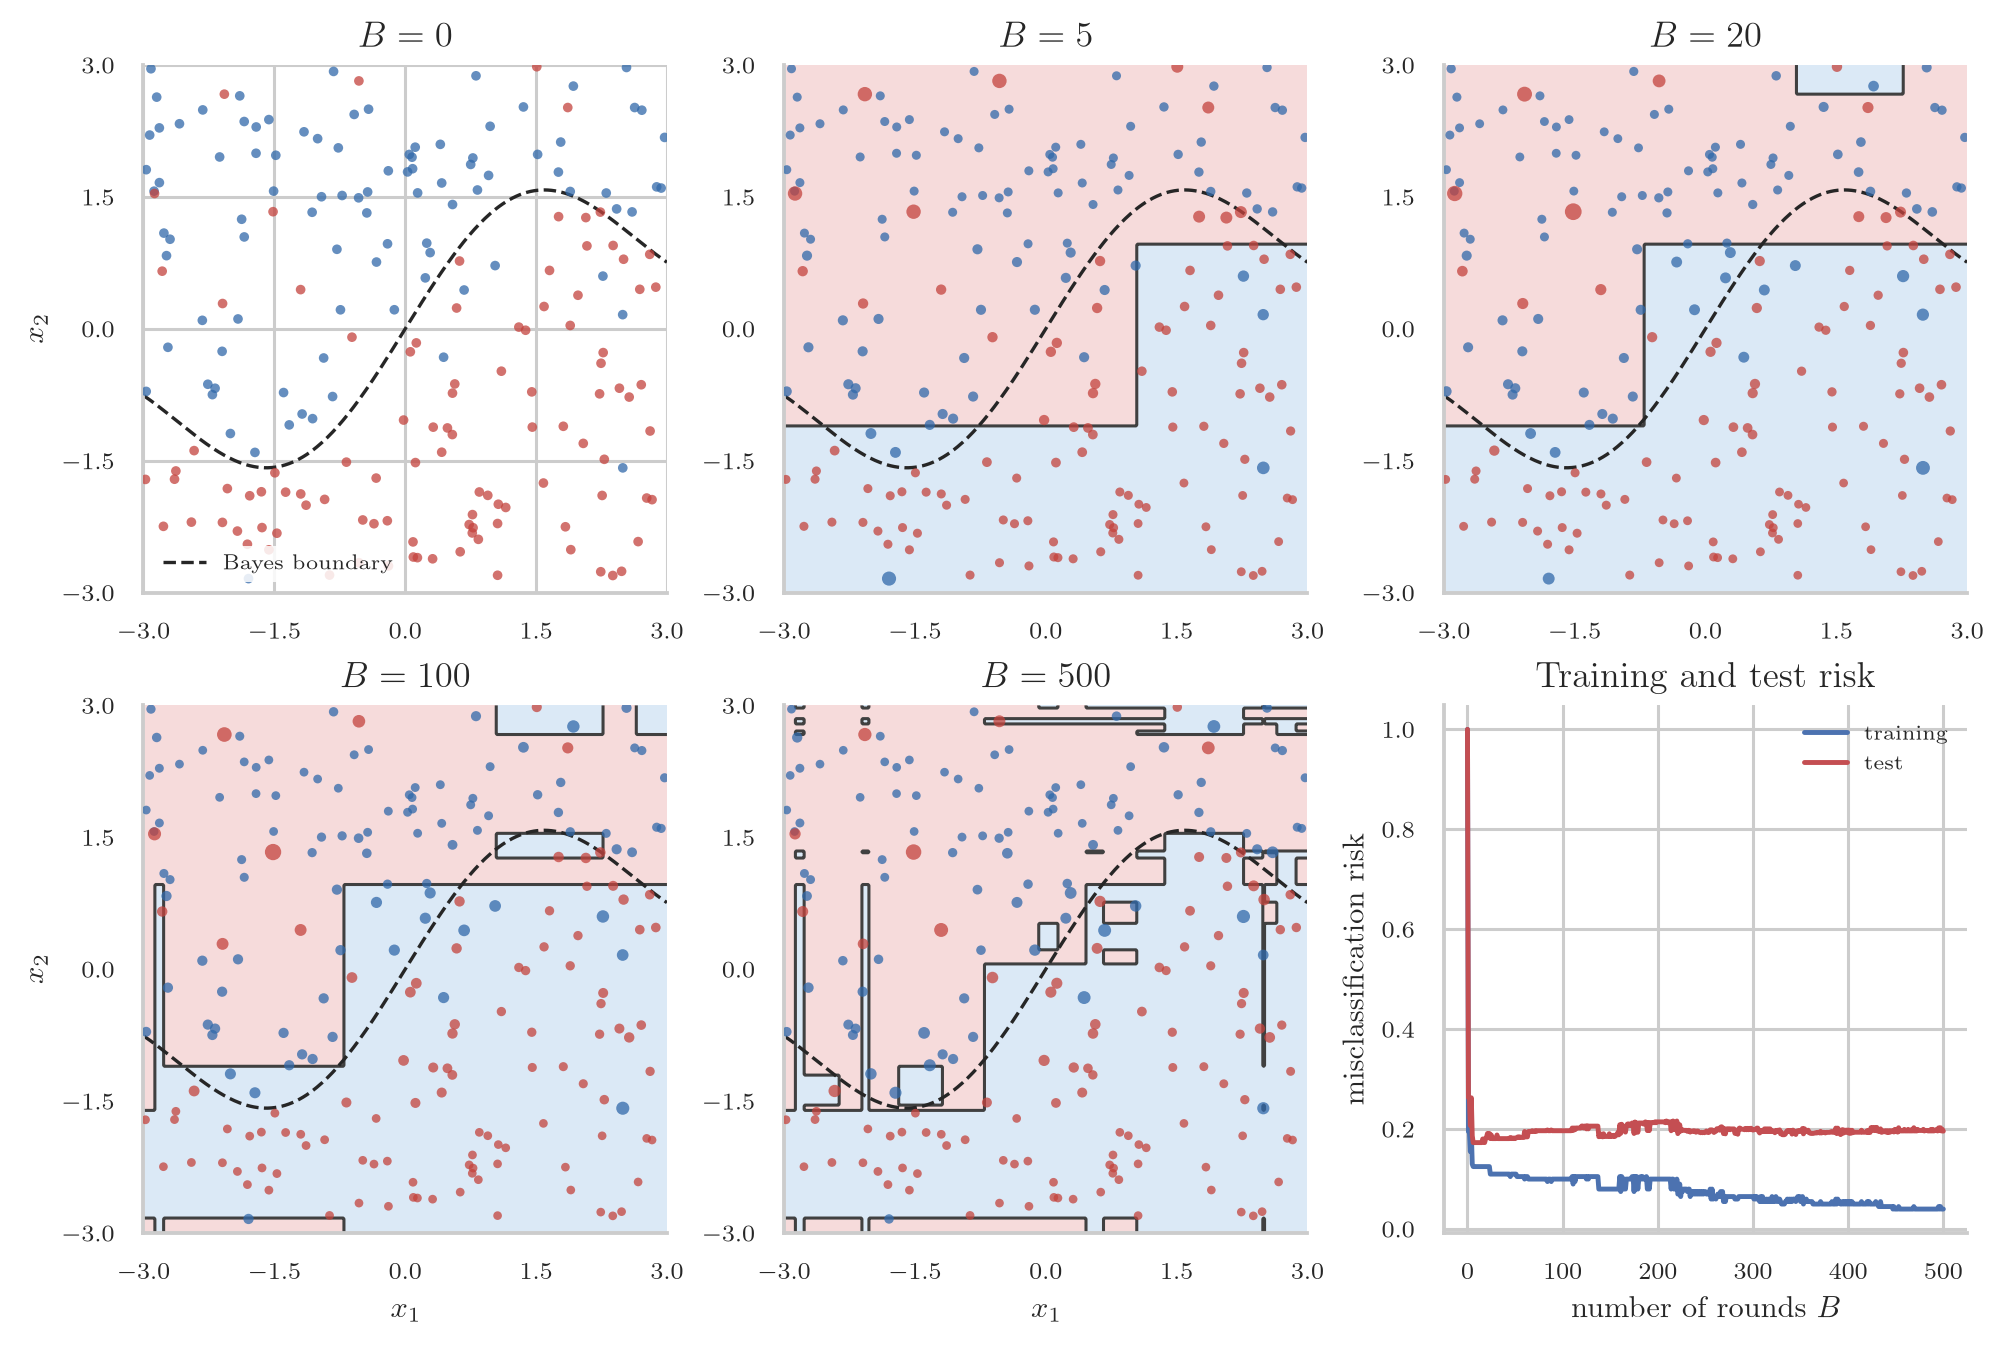
We remark in passing that it can be shown that with \(\eta=1\), if \(\err_b \le 1/2 - \gamma\) for some fixed \(\gamma > 0\) and all \(b\), then the training risk of \(\sign(f_B)\) under zero-one loss is at most \(e^{-2\gamma^{2}B}\). Thus, the bound falls geometrically in \(B\). Consequently, classifiers that are each only slightly better than guessing can drive the training error to zero. Thus, the training risk cannot be used to choose \(B\); use the validation risk as in Section 3.6.
5.3 Exercises
This chapter derives several gradient descent update rules (OLS, the sigmoid model, cross-entropy) by the same three-step recipe. What is it?
Solution
Solution, for real
Write the loss \(\lscr(\theta; x,y)\) on a single sample; differentiate it with respect to each parameter using the chain rule; average the result over \(\Tset\) to get \(\nabla\hat R_{\Tset}(\theta)\), then insert it into the update rule (5.1.1).
Why does gradient descent step opposite to the gradient rather than in some other direction, and what goes wrong if the learning rate \(\eta\) is chosen too large or too small?
Solution
Solution, for real
By the Taylor argument before (5.1.1), stepping opposite the gradient makes the first-order change in \(\hat R_{\Tset}\) as negative as possible. Too small an \(\eta\) needs many iterations to converge; too large an \(\eta\) breaks the Taylor approximation and the iterates can overshoot and diverge.
Suppose one feature is measured in meters and another in kilometers. Why does this slow down gradient descent, and what is the standard fix?
Solution
Solution, for real
A single \(\eta\) must respect the largest curvature among all directions; a feature with a much larger \(\overline{x(j)^{2}}\) forces a small \(\eta\) that leaves the other directions moving very slowly, so convergence takes many more iterations. Standardizing the features before fitting puts the curvatures on one scale, so the eigenvalues of the Hessian lie closer together; see the condition-number discussion after (5.1.2).
Take the training set \(\Tset = \set{(1,1), (2,3)}\) and a single feature, so \(\theta = (\beta_{0},\beta_{1})\). Starting from \(\theta^{(0)} = (0,0)\) with \(\eta = 0.1\), compute \(\theta^{(1)}\) using (5.1.2).
Solution
Solution, for real
At \(\theta^{(0)}\), \(\hat y^{(0)}(x) = 0\) for both samples, so the errors are \(-1\) and \(-3\), and \(\eta/|\Tset| = 0.05\). Then \(\beta_{0}^{(1)} = 0 - 0.05\rb{(-1)+(-3)} = 0.2\) and \(\beta_{1}^{(1)} = 0 - 0.05\rb{(-1)(1)+(-3)(2)} = 0.35\).
Apply one step of gradient descent to the loss \(\lscr(y,a) = (y-a)^{4}\), optimizing over the quadratic model \(\hat y = \beta_{0} + \beta_{1} x + \beta_{2} x^{2}\). Use the single-sample training set \(\Tset = \set{(1,2)}\), starting point \(\theta^{(0)} = (0,0,0)\), and \(\eta = 0.01\).
Solution
Solution, for real
By the chain rule, \(\partial \lscr/\partial \beta_{j} = -4(y-\hat y)^{3}\,x^{j}\) (with \(x^0=1\)). At \(\theta^{(0)}\), \(\hat y = 0\), so \(y-\hat y=2\) and every partial derivative equals \(-4\cdot 2^{3} = -32\) (since \(x=1\)). Hence \(\theta^{(1)} = \theta^{(0)} - 0.01\cdot(-32,-32,-32) = (0.32, 0.32, 0.32)\).
Compare a hesitant prediction \(\hat y = 0.5\) with a confidently wrong prediction \(\hat y = 0.999\), both for a true label \(y=0\). Compute the squared-loss gradient factor \((\hat y-y)\hat y(1-\hat y)\) in both cases and explain what this shows about saturation.
Solution
Solution, for real
For \(\hat y=0.5\): \(0.5\cdot 0.5\cdot 0.5 = 0.125\). For \(\hat y=0.999\): \(0.999 \cdot 0.999 \cdot 0.001 \approx 0.001\). The confidently wrong prediction updates the parameters over a hundred times more slowly, because \(\sigma\) is nearly flat far from \(0\); see the saturation discussion after (5.1.4).
Moving from squared loss to the binary cross-entropy loss for the same sigmoid model, the factor \(\hat y(1-\hat y)\) disappears from the gradient. What effect does this have on how a confidently wrong sample is treated?
Solution
Solution, for real
Compare (5.1.4) with the cross-entropy update: the gradient becomes just the prediction error \(\hat y - y\), so a confidently wrong sample now contributes the largest possible correction instead of being almost ignored. Saturation is gone.
What is stochastic gradient descent, and in what sense does it still move in the right direction on average?
Solution
Solution, for real
It replaces the full gradient in (5.1.1) by the gradient of a single sample drawn uniformly from \(\Tset\). This is unbiased, \(\E{\nabla \lscr(\theta;X,Y)} = \nabla\hat R_{\Tset}(\theta)\), so each step is cheap but noisy.
Show that the mini-batch gradient (5.1.6) is an unbiased estimator of the full gradient \(\nabla\hat R_{\Tset}(\theta)\).
Solution
Solution, for real
Since each sample in the batch \(\Bset\) is drawn uniformly from \(\Tset\), \(\E{\nabla\lscr(\theta;X,Y)} = \nabla\hat R_{\Tset}(\theta)\) for every term in the sum, and averaging unbiased terms is unbiased, so \(\E{\nabla\hat R_{\Bset}(\theta)} = \nabla\hat R_{\Tset}(\theta)\).
How does mini-batching work, and why is it used rather than plain stochastic or full-batch gradient descent? If \(|\Tset|=1000\) and the batch size is \(64\), how many parameter updates make up one epoch, and why are the batches reshuffled every epoch?
Solution
Solution, for real
It averages the gradient over a small batch \(\Bset\) instead of one sample or all of \(\Tset\), trading cost against noise. One epoch needs \(\lceil 1000/64\rceil = 16\) updates. Reshuffling prevents the same samples from always appearing together in a batch; see the paragraph after (5.1.6).
Why is a boosted ensemble a sum of base learners rather than an average like a bag, and why does forward-stagewise fitting make boosting greedy?
Solution
Solution, for real
Each round adds a correction to the current prediction function rather than combining independent fits, (5.2.2); since a term, once added, is never revisited, nothing guarantees that \(f_B\) is the best possible sum of \(B\) members of \(\Hset\); see the discussion around (5.2.1).
What are the three steps of gradient boosting?
Solution
Solution, for real
Each round: compute the pseudo-residuals (5.2.3), fit a base learner to them (5.2.4), and choose a scale factor by line search (5.2.5); see Alg. 5.2.1.
In gradient boosting, what are pseudo-residuals, and what are they used for?
Solution
Take the regression training set \(\Tset = \set{(0,1),(1,3),(2,2)}\) and square loss. Compute \(f_0\) and the first-round residuals \(\rscr_i^{(1)}\).
Solution
Solution, for real
By (5.2.6), \(f_0 = \bar y = (1+3+2)/3 = 2\). The residuals are \(\rscr_i^{(1)} = y_i - f_0\): \(-1, 1, 0\); see Section 5.2.2.
For regression boosting with squared loss and a least-squares regression tree as base learner, why does the line search (5.2.5) always give \(\rho_b = 1\)?
Solution
Solution, for real
A least-squares tree stores the mean residual on each leaf, so on leaf \(t\), \(\sum_{i\in \Tset_t} \rscr_i^{(b)} = |\Tset_t| c_t\); this makes \(\sum_i \rscr_i^{(b)} h_b(x_i) = \sum_i h_b(x_i)^2\), the ratio defining \(\rho_b\) in Section 5.2.2, equal to \(1\).
The training risk of a boosted regression model keeps falling as \(B\) grows. Why can \(B\) not be chosen from the training risk alone?
Solution
Solution, for real
Once the added trees start fitting noise specific to the training samples, the validation risk rises again even though the training risk keeps falling; \(B\) must instead be chosen by validation risk; see Section 5.2.2.
What is the margin \(yf(x)\) of a sample \((x,y)\) in AdaBoost, and what does its sign tell you?
Solution
Solution, for real
The sign of \(yf(x)\) says whether the sign of the score matches the label, so whether the classification is correct; see Section 5.2.3.
Applying gradient boosting to classification with \(y\in\set{-1,+1}\), one can use the exponential loss \(\lscr(y,f(x)) = e^{-yf(x)}\). Why this loss, rather than zero-one loss directly?
Solution
In AdaBoost, why does a misclassified sample’s weight increase after a round, and how does this affect the next base learner that gets fitted?
Solution
Solution, for real
The weight update (5.2.15) multiplies a correctly classified sample’s weight by a factor below \(1\) and a misclassified one’s by a factor above \(1\). Since the next classifier is chosen to minimize the weighted error (5.2.11), it is pushed to pay more attention to the samples the current ensemble still gets wrong.
Why must every base learner in AdaBoost satisfy \(\err_b < 1/2\)?